When candidate evaluation is the expensive part of a search, distributing that work can open room for a larger experiment. EvoX’s experimental guide of April 23, 2025 explains the path introduced that March: split the population across processes, then gather fitness before the algorithm updates.
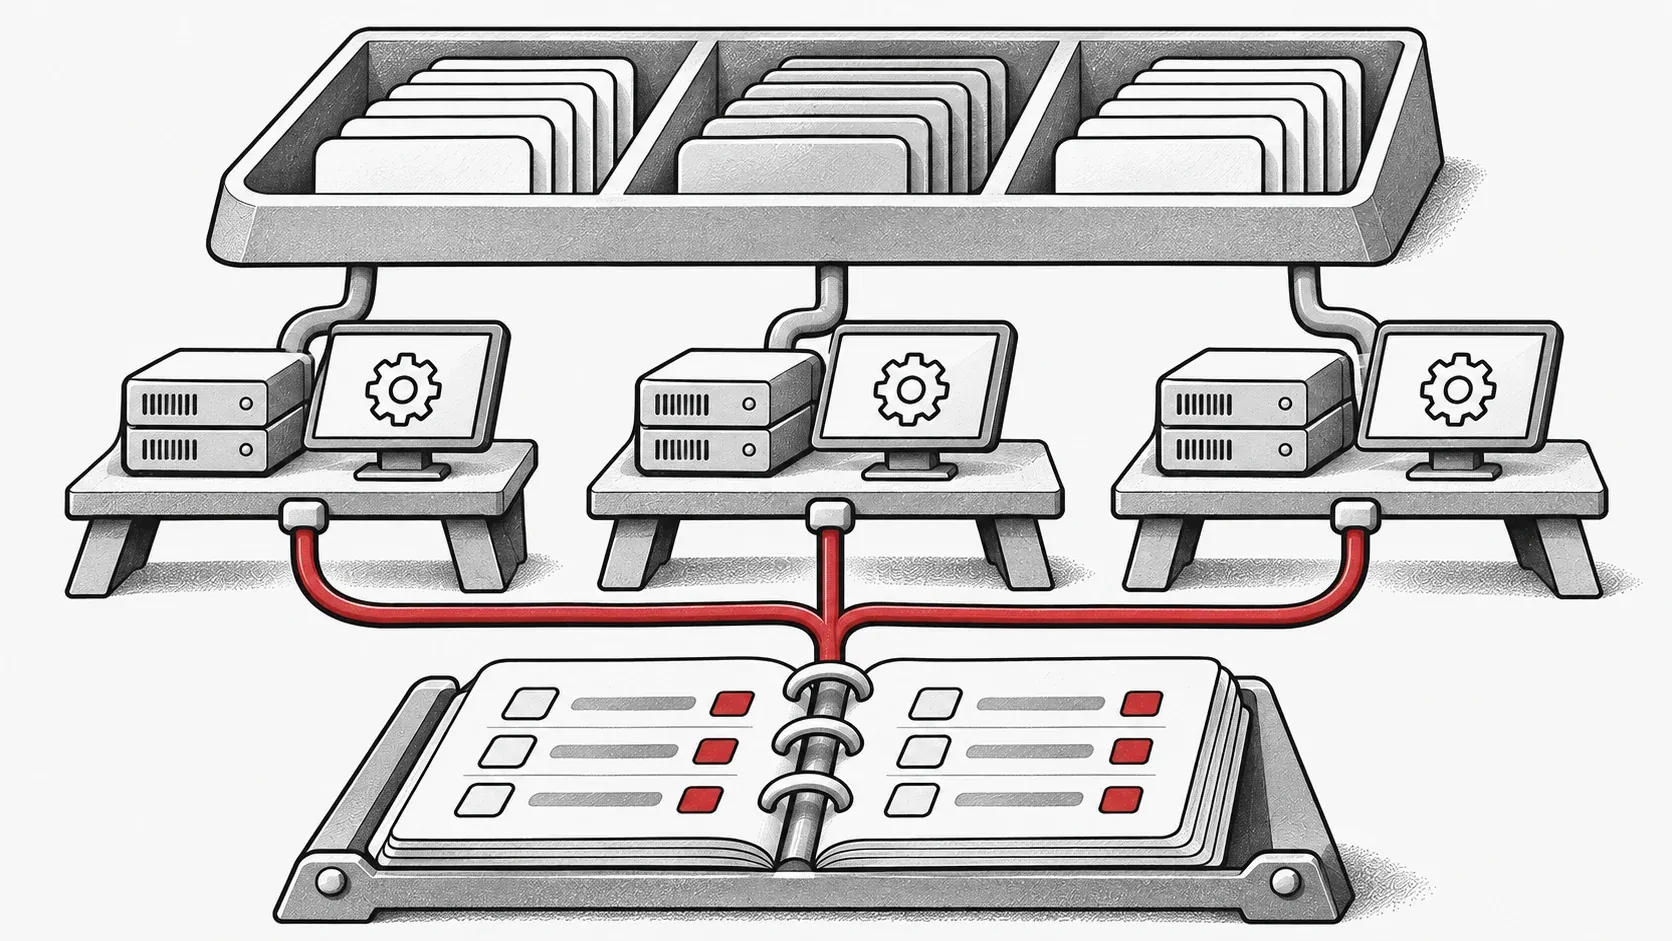
Separate evaluations, shared population feedback.
Distribute evaluation, then reunite feedback
The implementation extends StdWorkflow with distributed execution options. During evaluation, the population is split along its candidate dimension according to process rank. Each process evaluates its assigned candidates; fitness values are then gathered and concatenated before they return to the algorithm’s update path. StdWorkflow
This is distributed evaluation within a coordinated workflow. It is different from launching independent searches on separate machines and comparing their final answers. A costly simulation or objective function is a plausible use case, provided its evaluation can operate on the assigned candidate batches and the execution environment is configured correctly.
Reproducibility is part of setup
The guide emphasizes setting random seeds before Torch or NumPy operations and describes launching processes with torch.distributed or torchrun. The implementation isolates the random-number-generator state around problem evaluation. Consistent initialization matters because processes must maintain compatible search state while evaluating different parts of the population. 2025-04-23
Measure the complete generation
Compare a single-process baseline with the distributed run using the same objective, seed and population budget. Record complete generation time, including communication, and check candidate-to-fitness ordering. The quickstart introduces the workflow to establish before adding devices.